AlbumentationsX vs Torchvision
Compare AlbumentationsX with Torchvision transforms: API differences, RGB image benchmark results, and a PyTorch migration guide.
What Is Different?
Torchvision is the native augmentation layer for the PyTorch ecosystem. AlbumentationsX is framework-independent and optimized around NumPy/OpenCV image augmentation before tensors enter the model.
- Torchvision commonly operates on PIL images or tensors; AlbumentationsX operates on NumPy arrays and can emit PyTorch tensors with ToTensorV2.
- Torchvision integrates tightly with PyTorch datasets and model examples; AlbumentationsX focuses on faster CPU augmentation and richer computer-vision target handling.
- AlbumentationsX pipelines pass named targets such as image, mask, bboxes, and keypoints; Torchvision v1-style pipelines are mostly image-first unless you use the newer tv_tensors stack.
- AlbumentationsX tends to be easier when geometric transforms must stay consistent across masks, boxes, and keypoints.
RGB input pipeline results
Every path reads RGB JPEGs, prepares the recipe, and delivers a synchronized CUDA batch. CPU and GPU labels identify where augmentation runs; normalization runs on GPU for every path.
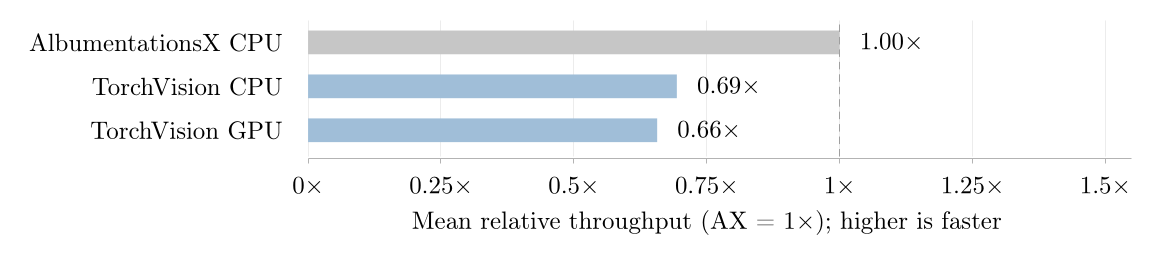
| Measured path | Throughput / AX | GPU memory (MiB) |
|---|---|---|
| AlbumentationsX CPU | 1.00× | 1,852 |
| TorchVision CPU | 0.69× | 1,814 |
| TorchVision GPU | 0.66× | 1,972 |
Each comparison uses its own shared recipe set. Averages from different sets cannot rank all libraries. The table below includes every measured recipe for these paths, including recipes outside the summary set. Recipe names are shortened; hover over a name for its full pipeline.
Higher throughput is better. Values are medians across seeds. Hover for the observed range. A dash means no measured result.
| R01Resize224 | 4,751 | 3,671 | 3,852 |
|---|---|---|---|
| R02RandomCrop224 | 4,740 | 4,424 | 4,375 |
| R03RandomResizedCrop | 4,785 | 3,518 | 3,558 |
| R04HorizontalFlip | 4,723 | 4,207 | 4,374 |
| R05VerticalFlip | 4,907 | 4,319 | 4,594 |
| R06Pad+RandomCrop224 | 4,397 | 3,685 | 3,626 |
| R07Rotate | 3,352 | 2,585 | 1,535 |
| R08Affine | 3,049 | 2,384 | 1,478 |
| R09Perspective | 2,879 | 2,179 | 886 |
| R10Elastic | 1,990 | 236 | 22 |
| R11ColorJitter | 3,523 | 1,203 | 731 |
| R12ChannelShuffle | 5,026 | 4,225 | 4,337 |
| R13Grayscale | 5,157 | 3,891 | 4,387 |
| R14RGBShift | 4,348 | — | — |
| R15GaussianBlur | 4,679 | 2,447 | 2,811 |
| R16GaussianNoise | 3,288 | — | — |
| R17Invert | 5,076 | 4,067 | 4,430 |
| R18Posterize | 5,110 | 4,336 | 4,453 |
| R19Solarize | 4,607 | 3,671 | 4,520 |
| R20Sharpen | 4,223 | 2,117 | 3,239 |
| R21AutoContrast | 4,263 | 2,687 | 3,859 |
| R22Equalize | 3,986 | 3,064 | 1,591 |
| R23Erasing | 4,938 | 4,010 | 2,907 |
| R24JpegCompression | 4,232 | 3,448 | — |
| R25RandomGamma | 4,969 | — | — |
| R26PlankianJitter | 4,538 | — | — |
| R27MedianBlur | 3,805 | — | — |
| R28MotionBlur | 4,223 | — | — |
| R29CLAHE | 2,373 | — | — |
| R30Brightness | 4,622 | 3,823 | 4,434 |
| R31Contrast | 4,642 | 3,377 | 3,333 |
| R32Blur | 4,821 | — | — |
| R33ChannelDropout | 4,972 | — | — |
| R34LinearIllumination | 3,866 | — | — |
| R35CornerIllumination | 4,090 | — | — |
| R36GaussianIllumination | 3,930 | — | — |
| R37Hue | 4,274 | — | — |
| R38PlasmaBrightness | 2,461 | — | — |
| R39PlasmaContrast | 2,162 | — | — |
| R40PlasmaShadow | 2,489 | — | — |
| R41Rain | 4,069 | — | — |
| R42SaltAndPepper | 4,147 | — | — |
| R43Saturation | 4,136 | — | — |
| R44Snow | 3,857 | — | — |
| R45OpticalDistortion | 3,110 | — | — |
| R46Shear | 2,658 | — | — |
| R47ThinPlateSpline | 858 | — | — |
| R48PhotoMetricDistort | 3,369 | 1,170 | 670 |
| R49ColorJiggle | 3,526 | 1,221 | 742 |
| R50LongestMaxSize+RandomCrop224 | 3,658 | — | — |
| R51SmallestMaxSize+RandomCrop224 | 3,221 | — | — |
| R52Transpose | 4,942 | — | — |
| R53RandomRotate90 | 5,002 | — | — |
| R54RandomJigsaw | 4,662 | — | — |
| R55EnhanceEdge | 4,389 | — | — |
| R56EnhanceDetail | 4,720 | — | — |
| R57UnsharpMask | 3,120 | — | — |
Measurement setup and limits
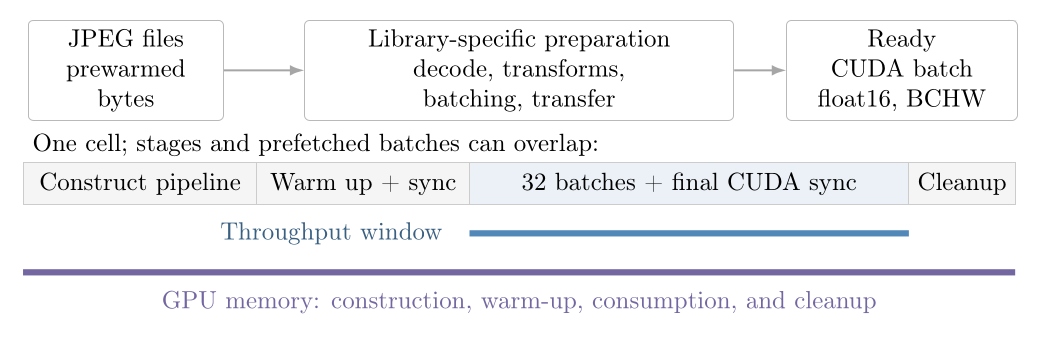
g2-standard-16, nvidia-l4; 10,000 selected ImageNet JPEGs. Batch size 256, 15 workers, prefetch factor 2; persistent workers enabled. Output: cuda float16, BCHW 256×3×224×224.
Seeds: 137, 138, 139. Each observation follows 1 warm-up batch and times 32 batches, ending with CUDA synchronization. Pipeline construction and worker startup are outside throughput timing; prefetch effects remain. JPEG files are prewarmed, so this measures filesystem reads and decoding with a warm page cache.
NVML samples peak process GPU memory every 50 ms, from pipeline construction through final synchronization and cleanup. Brief peaks can be missed. The measurements include no model and do not establish training speed or augmentation quality. Seeds do not guarantee identical augmentation draws across libraries. Observed ranges describe variation between runs; they are not confidence intervals.
In this published run, DALI Crop includes resizing the short side, and DALI Affine omits rotation and shear.
Run 3f8e2e315710528399b8e82e2359ab85c58c809644595b68a92fb9d83492cc8c · 759 measurements · measured source 5fc35f6 · machine-readable results · paper and methodology. This is the run reported in the paper.
Conversion Guide
In PyTorch projects, the usual migration is to keep your Dataset and DataLoader, replace torchvision.transforms with AlbumentationsX, then finish with ToTensorV2.
- Read images as NumPy arrays, usually with OpenCV plus BGR to RGB conversion.
- Replace transform lists with A.Compose.
- For classification, return transformed['image'] after ToTensorV2.
- For detection or segmentation, pass masks, bboxes, labels, and keypoint params through Compose instead of updating them manually.
from torchvision import transforms

transform = transforms.Compose([
    transforms.RandomHorizontalFlip(p=0.5),
    transforms.ColorJitter(brightness=0.2, contrast=0.2),
    transforms.ToTensor(),
])

image = transform(pil_image)import albumentations as A
from albumentations.pytorch import ToTensorV2
transform = A.Compose([
A.HorizontalFlip(p=0.5),
A.RandomBrightnessContrast(brightness_limit=0.2, contrast_limit=0.2, p=0.5),
ToTensorV2(),
])
image = transform(image=image_np)["image"]Use AlbumentationsX When
- PyTorch training pipelines where CPU augmentation speed matters.
- Detection, segmentation, keypoints, and multi-input augmentation where targets must stay aligned.
- Projects that want the same augmentation library across PyTorch, TensorFlow, Keras, and custom training loops.
Use Torchvision When
- Simple PyTorch classification baselines that already use torchvision examples.
- Tensor-native workflows that rely on torchvision transforms, tv_tensors, or PyTorch-only deployment assumptions.